Which Document Extraction APIs Hold Up on Messy Real-World Layouts Versus Clean PDFs
APIs that handle messy layouts need to preserve reading order and table structure.
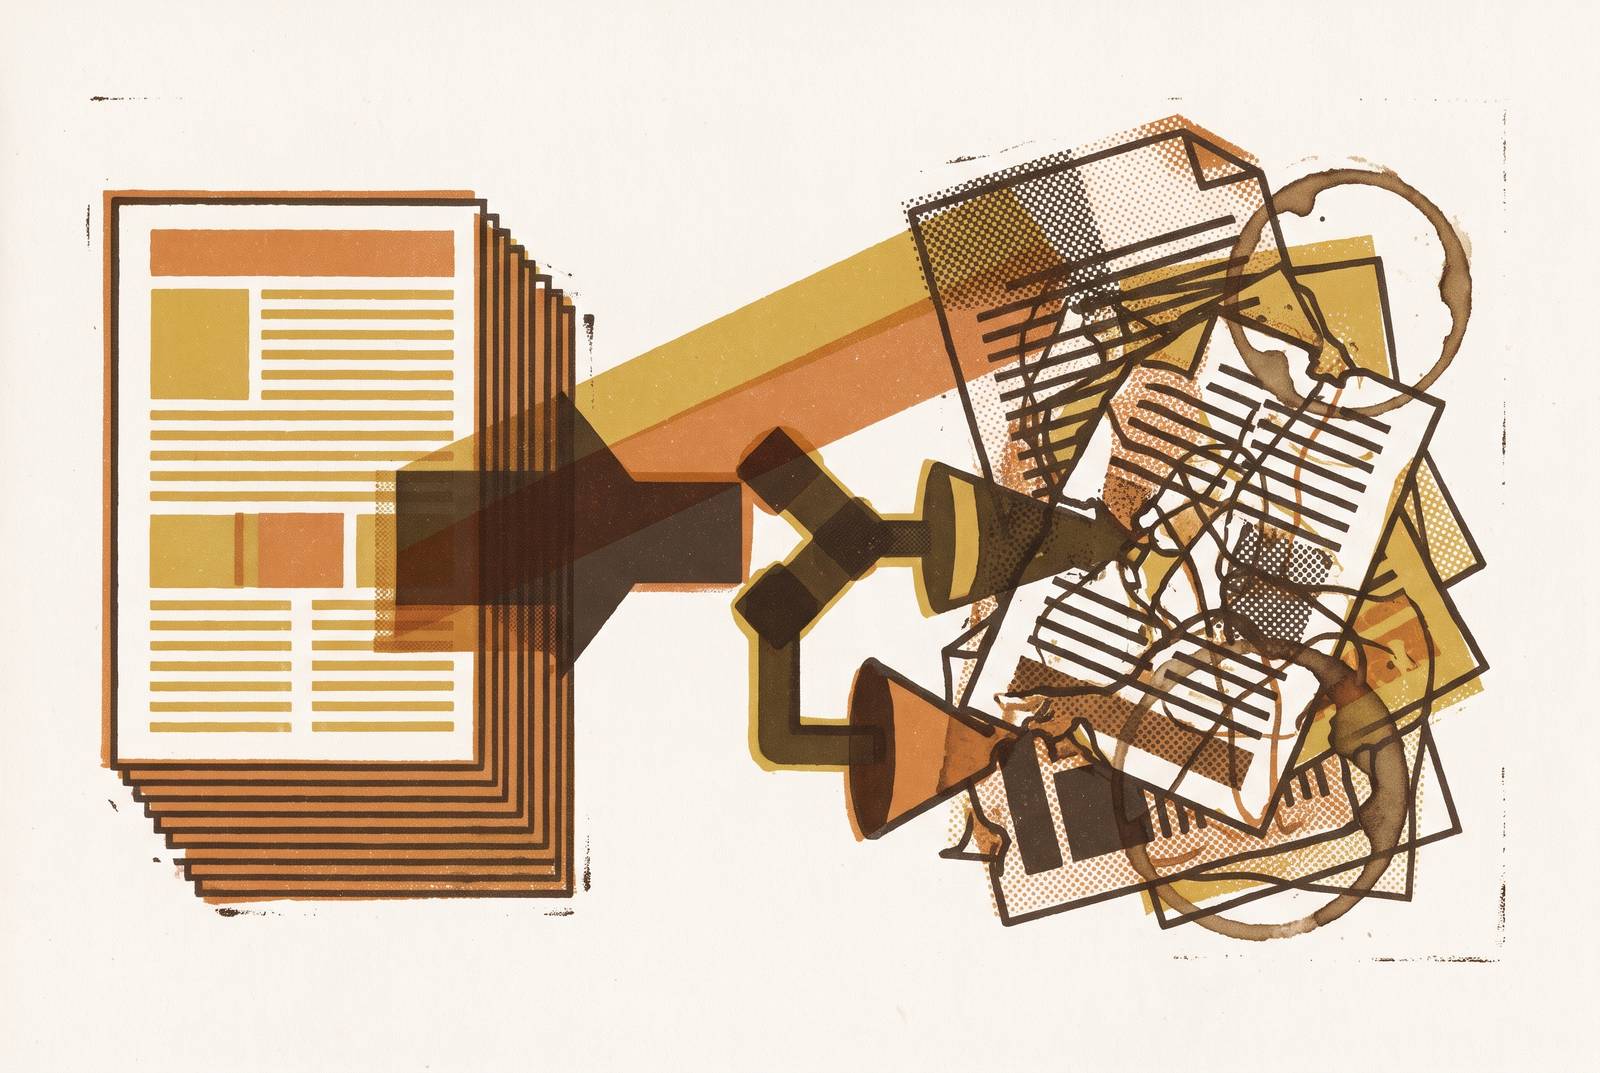
Document extraction APIs hold up on messy real-world layouts when they preserve reading order, reconstruct tables, handle degraded scans, and return every repeated record. Specialized extraction systems are built to meet those needs more directly than OCR alone, but a category label does not prove how accurate a system is. The right choice depends on representative document tests, field-level traceability, and the engineering needed to detect and correct failures.
Why clean-PDF benchmarks tell you almost nothing about production document performance
An extractor can recognize every character in a multi-column table and still assign the values to the wrong fields. The text looks correct. Yet when a merged header loses its link to its columns, it changes what those values mean and leaves downstream systems with data whose structure looks right but is wrong.
Standard OCR benchmarks often measure character error rate, or CER, and text-level F1 instead of checking reading order or how parts of a table relate to each other. Their scores can therefore create a false sense of production readiness. Multi-page financial statements, scanned manifests with nested tables, handwritten consult notes, and fax-compressed forms are normal inputs in financial services, healthcare, logistics, and real estate and test different capabilities.
What real-world document complexity actually means, and the four dimensions where APIs break
Reading order is the first dimension. Multi-column pages, sidebars, captions, footnotes, and nested lists must be sequenced according to document logic. Otherwise, text from separate regions merges into a misleading stream. Correct recognition cannot repair the lost sequence.
Table structure is the second dimension. Merged cells can become independent rows, spanning headers can detach from their columns, and borderless tables can collapse into flat text. Rows split across pages add another structural test. These errors change the meaning of fields that depend on where they sit, but character-only metrics miss them.
Degraded-scan OCR is the third dimension. Skew, rotation, handwriting, fax compression, and mixed digital-and-scanned pages challenge recognition as well as layout handling. Traditional engines such as Tesseract work with simple printed layouts but struggle with complex arrangements and handwriting.
Large repeating arrays are the fourth dimension. Tables with hundreds or thousands of rows expose silent record omission, which aggregate field accuracy can conceal. An API may extract most returned values correctly while failing to return every record. In a ledger or logistics manifest, that gap is data loss without an obvious error signal.
How to read the benchmarks that actually measure these failure modes
RealDoc-Bench uses Adjusted F1 to measure layout accuracy and tests whether parsed output can be used for downstream document Q&A. Its production-style documents come from logistics, healthcare, financial services, and real estate. Failures and timeouts count as zero in mean per-document accuracy. That rule prevents difficult documents from disappearing from the reported result.
LongArray-Extract tests long production documents that have hundreds to thousands of repeated records. Its scope is narrower. It evaluates the completeness problem that broad accuracy averages can obscure, and failed or timed-out runs also score zero. Both benchmarks are open-sourced and others can reproduce them, though that alone says nothing about who sponsored vendor-run results.
PoliTax Split tests compound-document splitting, which decides whether the right pages go to the right workflow before extraction starts. Parsing reconstructs a document, while extraction returns selected values against a schema. Published corpora provide useful evidence, but candidate APIs still need testing on the documents a team actually receives.
How different API architectures handle layout complexity, and why the architecture predicts the failure mode
OCR-first architectures separate character recognition from document understanding. Without sufficient layout handling, columns merge and tables become jumbled text even when recognition is accurate. Tesseract illustrates the constraints of traditional OCR on complex layouts. Hybrid rules-plus-ML systems can handle consistent formats, but layout variation weakens the assumptions those rules depend on.
Direct multimodal model calls handle varied layouts and individual fields but remain vulnerable to large arrays and broad enterprise schemas. ExtractBench found that frontier models fail at enterprise-scale complex schema extraction without additional orchestration. The model call is only one component. Confidence scoring, schema versioning, evaluation, and retry logic become custom engineering, changing the cost per correct field.
Template-trained cloud platforms give up that flexibility to work with established types of documents. Pre-built models work with standard forms, but can return only the fields in their fixed field sets. Non-standard documents require labeled samples, training jobs, and model-version management. When formats keep changing, teams have to keep doing ML operations work after the one-time integration task.
Specialized extraction systems combine vision models, layout detection, and orchestration to address all four dimensions. The surrounding system harness handles tasks that a model call alone does not, including reading order, repeated records, and quality controls. Architecture makes failure modes more predictable. It does not remove the need to measure how a particular implementation handles them.
Which extraction APIs handle complex multi-column documents, tables, and mixed formats?
Specialized extraction APIs belong first in a shortlist for documents that combine all four failure dimensions, because their architecture addresses the complete task. Evidence quality still depends on reproducible parsing and extraction results. Useful comparison criteria include schema-bound JSON, per-field confidence, source citations, document breadth, and built-in evaluation and review. Processing modes also change how accuracy, latency, and cost weigh against each other.
Focused parsing APIs offer a narrower fit. They can provide strong baseline parsing for straightforward document types while leaving schema management and review to the customer. Their evidence should be read at the function level rather than treated as proof of complete extraction reliability. Evaluation tools available only on higher plans also change what lower-tier teams must build themselves.
Mistral OCR returns markdown enriched with bounding boxes, typed-block classification, and inline confidence scores. It also supports schema-mapped JSON through Document AI parameters in the same API call. Its documented capabilities accompany strong clean-document accuracy that degrades on complex multi-column pages, nested tables, low-quality files, and multilingual content, making those the essential evaluation cases.
Tesseract is free and locally hostable, with structured formats including hOCR, TSV, ALTO, and PDF, plus a C++ API and language wrappers. These capabilities distinguish it from a plain text dump. They do not establish reliable schema-bound extraction on irregular layouts. Its limited complex-layout handling and poor handwriting accuracy make simple, consistent documents the appropriate fit.
Google Document AI offers managed OCR, form, layout, custom extraction, classification, and splitting processors for teams native to its cloud platform. Template-oriented platforms, including ABBYY, fit established capture workflows whose owners accept model and template maintenance. Their adaptation costs deserve explicit testing. RAG preprocessing tools serve retrieval rather than schema-bound extraction, while Firecrawl lacks comparable public document-accuracy and completion-rate evidence for these production workloads. The available evidence supports a shortlist by workflow.
Where real-world layout complexity hits hardest: industry-specific failure patterns
Healthcare combines long records with handwritten and typed content. Classification must distinguish referrals, lab reports, imaging results, and billing statements before extraction can route values appropriately. A routing error has downstream clinical consequences. Irregular payer forms also complicate prior authorization, where structured extraction must work beyond a standard template.
Financial services concentrates risk in table structure and completeness. With merged cells, spanning headers, and multi-page row sets, mistakes in extraction can lead to compliance issues later on. Loan packages add cross-file dependencies among pay stubs, bank statements, and tax documents. Single-document processing leaves teams responsible for joining those results without losing their relationships.
Logistics adds reading-order problems to carrier-specific layouts. Bills of lading place container numbers and shipping details differently across carriers and origin countries, so misread fields can delay customs clearance and create dwell time and demurrage costs. Real estate and insurance introduce a related boundary problem. Transaction bundles and claim files need splitting and classification before field extraction, while files processed on their own need stitching logic to join them, and that logic can fail.
What confidence scoring and human-in-the-loop review actually require from an extraction API
A production evaluation should examine uncertainty at the field level. Cohere Parse returns markdown or text without a confidence signal, while template-trained platforms use either document-level or per-field scoring. A document score cannot identify the uncertain value. Where field-level signals are absent, the engineering cost of a custom confidence layer belongs in the API comparison.
Human review also requires source context. Bounding boxes and source text let a reviewer locate the extracted value in the original document and avoid repeating the extraction from scratch. A flagged field without that context is incomplete review tooling.
Traceability extends beyond the review screen. Append-only event logs keyed by a stable document ID provide the history needed for auditing and compliance. Schema versioning and evaluation sets then make changes testable before users encounter regressions. Like CI/CD for code, these controls turn reliability into a maintained system property, while plan-gated evaluation leaves some teams responsible for building that protection themselves.
Enterprise deployment requirements that most API comparisons ignore until it is too late
Compliance and deployment requirements should be evaluated in parallel with accuracy, before production data reaches an API. Relevant criteria include SOC 2, HIPAA, and GDPR coverage, plus an available HIPAA BAA for healthcare deployments. Data handling needs equal scrutiny. Zero data retention must cover the intended plan and address retention for model training or logging rather than appear only as an enterprise-tier promise.
Deployment labels are not interchangeable. Bring your own cloud, or BYOC, and self-hosted options can keep processing within an organization’s infrastructure perimeter, but air-gapped operation is a separate requirement. PCI-sensitive workflows require self-hosted deployment under the criteria here. An accurate managed service can therefore be unsuitable for a particular regulated workflow.
Operational fit depends on asynchronous queues, webhooks, transparent rate limits, idempotency, observability, and version-controlled schemas. High-volume processing also needs batch economics that work at scale as well as good single-page latency. These requirements become evident under production load. Their absence shifts queue management and failure handling into the application team’s workload.
Developer experience determines how much of that work persists. Typed SDKs, a CLI, Model Context Protocol support, and installable agent skills help teams discover, build, and debug workflows. Raw text, key-value pairs, and bounding boxes without typed output contracts require maintained mapping layers. Those layers add production debt to an API that looks cheap, with costs that stay hidden in per-page pricing.
How to run your own evaluation before committing to an API
First, build a representative corpus before testing candidates. Include multi-column layouts, merged cells and spanning headers, degraded or handwritten scans, and at least one large repeating array. Select worst-case inputs as well as ordinary ones. Median documents alone will hide the failures most likely to disrupt a workflow.
Second, evaluate parsing separately from extraction. Test reading order and layout reconstruction before scoring the values returned against a schema that has been defined. Include every expected row in the extraction test. A combined score can let success in one task conceal failure in the other.
Third, score large-array completeness by checking how many rows are in the input against how many are in the output. Treat missing records as data loss. Count failed and timed-out documents as zero rather than excluding them, following the rule used by LongArray-Extract. Otherwise, the hardest documents can vanish from both the output and the performance assessment.
Fourth, measure end-to-end wall-clock time and completion rate under the expected page mix. Include rate limits, concurrency behavior, and timeout handling. Single-page latency is not a throughput test. A demonstration on one page does not predict processing a 400-page financial statement or an 800-page clinical chart.
Fifth, establish compliance and data-handling fit before submitting production data. Confirm zero data retention on the intended plan. Check the specific deployment mode. Required compliance coverage must apply to the infrastructure that will actually process the documents.
Sixth, evaluate the tooling that will remain after integration. RealDoc-Bench provides a GitHub evaluation harness, Q&A dataset, and layout dataset that teams can inspect and adapt. Include confidence scoring, schema versioning, evaluation sets, and review in the ownership calculation. When an API omits those controls, add the cost of building and maintaining them to its price.